
CF1380B.Universal Solution
普及/提高-
通过率:0%
时间限制:2.00s
内存限制:256MB


AC君温馨提醒
该题目为【codeforces】题库的题目,您提交的代码将被提交至codeforces进行远程评测,并由ACGO抓取测评结果后进行展示。由于远程测评的测评机由其他平台提供,我们无法保证该服务的稳定性,若提交后无反应,请等待一段时间后再进行重试。
题目描述
Recently, you found a bot to play "Rock paper scissors" with. Unfortunately, the bot uses quite a simple algorithm to play: he has a string s=s1s2…sn of length n where each letter is either R, S or P.
While initializing, the bot is choosing a starting index pos (1≤pos≤n), and then it can play any number of rounds. In the first round, he chooses "Rock", "Scissors" or "Paper" based on the value of spos:
- if spos is equal to R the bot chooses "Rock";
- if spos is equal to S the bot chooses "Scissors";
- if spos is equal to P the bot chooses "Paper";
In the second round, the bot's choice is based on the value of spos+1. In the third round — on spos+2 and so on. After sn the bot returns to s1 and continues his game.
You plan to play n rounds and you've already figured out the string s but still don't know what is the starting index pos. But since the bot's tactic is so boring, you've decided to find n choices to each round to maximize the average number of wins.
In other words, let's suggest your choices are c1c2…cn and if the bot starts from index pos then you'll win in win(pos) rounds. Find c1c2…cn such that nwin(1)+win(2)+⋯+win(n) is maximum possible.
最近,你发现了一个可以和你玩“石头剪刀布”的机器人。不幸的是,这个机器人采用了一种非常简单的算法:它拥有一串长度为 n 的字符串 s=s1s2…sn,其中每个字符均为 R、S 或 P。
在初始化阶段,机器人会选定一个起始索引 pos(满足 1≤pos≤n),之后它可以进行任意轮数的游戏。在第 1 轮中,机器人根据 spos 的值选择“石头”、“剪刀”或“布”:
- 若 spos=R,则机器人选择“石头”;
- 若 spos=S,则机器人选择“剪刀”;
- 若 spos=P,则机器人选择“布”。
在第 2 轮中,机器人的选择依据为 spos+1;在第 3 轮中,依据为 spos+2,依此类推。当到达 sn 后,机器人将循环回到 s1 并继续游戏。
你计划进行 n 轮游戏,且已知字符串 s,但尚不清楚机器人的起始索引 pos 是多少。然而,由于该机器人的策略过于单调乏味,你决定预先确定自己在每一轮中的出拳 c1c2…cn,以最大化获胜轮数的平均值。
换言之,假设你的出拳序列为 c1c2…cn,若机器人从索引 pos 开始,则你在该情形下将赢得 win(pos) 轮。请找出序列 c1c2…cn,使得 nwin(1)+win(2)+⋯+win(n) 达到可能的最大值。
输入格式
The first line contains a single integer t (1≤t≤1000) — the number of test cases.
Next t lines contain test cases — one per line. The first and only line of each test case contains string s=s1s2…sn (1≤n≤2⋅105; si∈R,S,P) — the string of the bot.
It's guaranteed that the total length of all strings in one test doesn't exceed 2⋅105.
第一行包含一个整数 t(1≤t≤1000)—— 表示测试用例的数量。
接下来的 t 行为测试用例,每行一个。每个测试用例仅有一行,包含一个字符串 s=s1s2…sn(1≤n≤2⋅105;si∈{R,S,P})—— 表示该机器人的出拳序列。
保证单次测试中所有字符串的总长度不超过 2⋅105。
输出格式
For each test case, print n choices c1c2…cn to maximize the average number of wins. Print them in the same manner as the string s.
If there are multiple optimal answers, print any of them.
对于每个测试用例,输出 n 个选择 c1c2…cn,以最大化获胜次数的平均值。输出格式需与字符串 s 相同。
若存在多个最优解,输出任意一个即可。
输入输出样例
输入#1
3
RRRR
RSP
S
输出#1
PPPP
RSP
R
说明/提示
In the first test case, the bot (wherever it starts) will always choose "Rock", so we can always choose "Paper". So, in any case, we will win all n=4 rounds, so the average is also equal to 4.
In the second test case:
- if bot will start from pos=1, then (s1,c1) is draw, (s2,c2) is draw and (s3,c3) is draw, so win(1)=0;
- if bot will start from pos=2, then (s2,c1) is win, (s3,c2) is win and (s1,c3) is win, so win(2)=3;
- if bot will start from pos=3, then (s3,c1) is lose, (s1,c2) is lose and (s2,c3) is lose, so win(3)=0;
The average is equal to 30+3+0=1 and it can be proven that it's the maximum possible average.
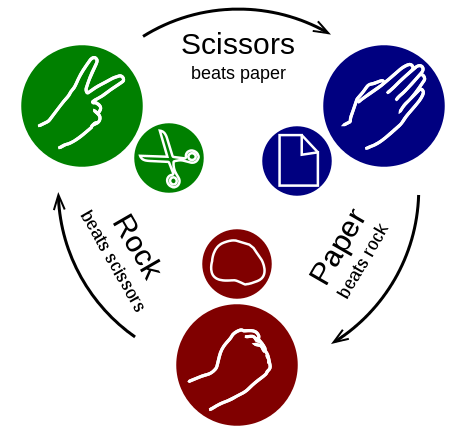
A picture from Wikipedia explaining "Rock paper scissors" game:
在第一个测试用例中,机器人(无论从何处开始)总会选择“石头”,因此我们总可以选择“布”。于是,在任何情况下,我们都将赢得全部 n=4 轮,故平均值也为 4。
在第二个测试用例中:
- 若机器人从 pos=1 开始,则 (s1,c1) 为平局,(s2,c2) 为平局,(s3,c3) 为平局,因此 win(1)=0;
- 若机器人从 pos=2 开始,则 (s2,c1) 为获胜,(s3,c2) 为获胜,(s1,c3) 为获胜,因此 win(2)=3;
- 若机器人从 pos=3 开始,则 (s3,c1) 为失败,(s1,c2) 为失败,(s2,c3) 为失败,因此 win(3)=0;
平均值为 30+3+0=1,且可以证明这是可能达到的最大平均值。
维基百科中解释“石头剪刀布”游戏的一张图片:
输入解题思路,AI测评打分。不知道怎么写?