

CF935D.Fafa and Ancient Alphabet
普及+/提高
通过率:0%
时间限制:2.00s
内存限制:256MB


AC君温馨提醒
该题目为【codeforces】题库的题目,您提交的代码将被提交至codeforces进行远程评测,并由ACGO抓取测评结果后进行展示。由于远程测评的测评机由其他平台提供,我们无法保证该服务的稳定性,若提交后无反应,请等待一段时间后再进行重试。
题目描述
Ancient Egyptians are known to have used a large set of symbols  to write on the walls of the temples. Fafa and Fifa went to one of the temples and found two non-empty words _S_1 and _S_2 of equal lengths on the wall of temple written one below the other. Since this temple is very ancient, some symbols from the words were erased. The symbols in the set
 have equal probability for being in the position of any erased symbol.
Fifa challenged Fafa to calculate the probability that _S_1 is lexicographically greater than _S_2. Can you help Fafa with this task?
You know that  , i. e. there were m distinct characters in Egyptians' alphabet, in this problem these characters are denoted by integers from 1 to m in alphabet order. A word x is lexicographically greater than a word y of the same length, if the words are same up to some position, and then the word x has a larger character, than the word y.
We can prove that the probability equals to some fraction  , where P and Q are coprime integers, and
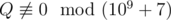 . Print as the answer the value
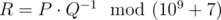 , i. e. such a non-negative integer less than 109 + 7, such that
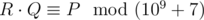 , where
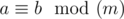 means that a and b give the same remainders when divided by m.
古埃及人以使用大量符号而闻名,他们用这些符号在神庙的墙壁上书写。法法(Fafa)和菲法(Fifa)参观了一座神庙,并在神庙墙壁上发现了两个非空单词 S1 和 S2,它们长度相等,且上下排列。由于该神庙极为古老,单词中部分符号已被擦除。被擦除位置上的符号等概率地取自符号集合 中的任意一个。
菲法向法法发起挑战:计算 S1 字典序严格大于 S2 的概率。你能帮法法解决这个问题吗?
已知 ,即古埃及字母表中共有 m 个互异字符;在本题中,这些字符按字典序依次记为整数 1 至 m。对于两个等长的单词 x 和 y,若它们在前若干位完全相同,而在第一个不同的位置上,x 对应的字符大于 y 对应的字符,则称 x 字典序大于 y。
我们可以证明该概率可表示为最简分数形式 ,其中 P 与 Q 互质,且 。请输出答案 ,即满足 0≤answer<109+7 的唯一非负整数,使得 ,其中符号 表示 a 与 b 对模 m 同余(即 a 和 b 除以 m 所得余数相同)。
输入格式
The first line contains two integers n and m (1 ≤ n, m ≤ 105) — the length of each of the two words and the size of the alphabet  , respectively.
The second line contains n integers _a_1, _a_2, ..., a__n (0 ≤ a__i ≤ m) — the symbols of _S_1. If a__i = 0, then the symbol at position i was erased.
The third line contains n integers representing _S_2 with the same format as _S_1.
第一行包含两个整数 n 和 m(1≤n,m≤105)——分别为两个单词的长度以及字母表大小 。
第二行包含 n 个整数 a1,a2,…,an(0≤ai≤m)——表示字符串 S1 中的符号。若 ai=0,则表示第 i 位的符号已被擦除。
第三行包含 n 个整数,以与 S1 相同的格式表示字符串 S2。
输出格式
Print the value 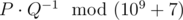 , where P and Q are coprime and
 is the answer to the problem.
输出值 ,其中 P 和 Q 互质,且 是该问题的答案。
输入输出样例
输入#1
1 2
0
1
输出#1
500000004
输入#2
1 2
1
0
输出#2
0
输入#3
7 26
0 15 12 9 13 0 14
11 1 0 13 15 12 0
输出#3
230769233
说明/提示
In the first sample, the first word can be converted into (1) or (2). The second option is the only one that will make it lexicographically larger than the second word. So, the answer to the problem will be 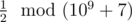 , that is 500000004, because
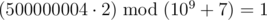 .
In the second example, there is no replacement for the zero in the second word that will make the first one lexicographically larger. So, the answer to the problem is 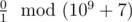 , that is 0.
在第一个样例中,第一个单词可以转换为 (1) 或 (2)。其中只有第二种选择能使它字典序大于第二个单词。因此,该问题的答案为 ,即 500000004,因为 。
在第二个样例中,第二个单词中的零无论替换成何值,都无法使第一个单词字典序大于第二个单词。因此,该问题的答案为 ,即 0。
输入解题思路,AI测评打分。不知道怎么写?