

CF523B.Mean Requests
普及/提高-
通过率:0%
时间限制:4.00s
内存限制:256MB


AC君温馨提醒
该题目为【codeforces】题库的题目,您提交的代码将被提交至codeforces进行远程评测,并由ACGO抓取测评结果后进行展示。由于远程测评的测评机由其他平台提供,我们无法保证该服务的稳定性,若提交后无反应,请等待一段时间后再进行重试。
题目描述
In this problem you will have to deal with a real algorithm that is used in the VK social network.
As in any other company that creates high-loaded websites, the VK developers have to deal with request statistics regularly. An important indicator reflecting the load of the site is the mean number of requests for a certain period of time of T seconds (for example, T = 60 seconds = 1 min and T = 86400 seconds = 1 day). For example, if this value drops dramatically, that shows that the site has access problem. If this value grows, that may be a reason to analyze the cause for the growth and add more servers to the website if it is really needed.
However, even such a natural problem as counting the mean number of queries for some period of time can be a challenge when you process the amount of data of a huge social network. That's why the developers have to use original techniques to solve problems approximately, but more effectively at the same time.
Let's consider the following formal model. We have a service that works for n seconds. We know the number of queries to this resource a__t at each moment of time t (1 ≤ t ≤ n). Let's formulate the following algorithm of calculating the mean with exponential decay. Let c be some real number, strictly larger than one.
// setting this constant value correctly can adjust
// the time range for which statistics will be calculated
double c = some constant value;
// as the result of the algorithm's performance this variable will contain
// the mean number of queries for the last
// T seconds by the current moment of time
double mean = 0.0;
for t = 1..n: // at each second, we do the following:
// a__t is the number of queries that came at the last second;
mean = (mean + a__t / T) / c;
Thus, the mean variable is recalculated each second using the number of queries that came at that second. We can make some mathematical calculations and prove that choosing the value of constant c correctly will make the value of mean not very different from the real mean value a__x at t - T + 1 ≤ x ≤ t.
The advantage of such approach is that it only uses the number of requests at the current moment of time and doesn't require storing the history of requests for a large time range. Also, it considers the recent values with the weight larger than the weight of the old ones, which helps to react to dramatic change in values quicker.
However before using the new theoretical approach in industrial programming, there is an obligatory step to make, that is, to test its credibility practically on given test data sets. Your task is to compare the data obtained as a result of the work of an approximate algorithm to the real data.
You are given n values a__t, integer T and real number c. Also, you are given m moments p__j (1 ≤ j ≤ m), where we are interested in the mean value of the number of queries for the last T seconds. Implement two algorithms. The first one should calculate the required value by definition, i.e. by the formula 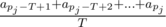 . The second algorithm should calculate the mean value as is described above. Print both values and calculate the relative error of the second algorithm by the formula
 , where approx is the approximate value, obtained by the second algorithm, and real is the exact value obtained by the first algorithm.
本题中,您将处理一个在 VK 社交网络中实际使用的算法。
正如所有构建高负载网站的公司一样,VK 的开发人员需要定期处理请求统计信息。反映网站负载的一个重要指标,是在某段时间 $ T $ 秒(例如,$ T = 60\ \text{秒} = 1\ \text{分钟} $,或 $ T = 86400\ \text{秒} = 1\ \text{天} $)内请求次数的平均值。例如,若该值急剧下降,则表明网站可能存在访问问题;若该值上升,则可能需分析增长原因,并在确有必要的前提下为网站增加服务器。
然而,即便是“计算某段时间内的请求平均数”这样看似自然的问题,在处理大型社交网络所产生的海量数据时,也可能成为一个挑战。因此,开发人员不得不采用一些原创性的技巧,以近似但更高效的方式解决问题。
我们考虑如下形式化模型:某服务运行 $ n $ 秒,已知每一时刻 $ t ( 1 \le t \le n $)对该资源的查询次数为 $ a_t $。下面定义一种带指数衰减的平均值计算算法。令 $ c $ 为某个严格大于 1 的实数。
// 正确设置该常数值可调节
// 统计所覆盖的时间范围
double c = some constant value;
// 算法执行完毕后,该变量将包含
// 截至当前时刻、过去 $ T $ 秒内的平均请求次数
double mean = 0.0;
for t = 1..n: // 每一秒执行如下操作:
// $ a_t $ 表示上一秒到达的请求数;
mean = (mean + a_t / T) / c;
因此,变量 mean 每秒均依据当秒到达的请求数 $ a_t $ 进行更新。通过一定的数学推导可以证明:若恰当地选取常数 $ c $,则 mean 的值将与真实平均值(即区间 $ t - T + 1 \le x \le t $ 内所有 $ a_x $ 的算术平均值)相差不大。
该方法的优势在于:仅需使用当前时刻的请求数,无需存储长时间跨度的历史请求数据;同时,它赋予近期值更大的权重,而对旧值赋予较小权重,从而能更快地响应数值的剧烈变化。
然而,在将这一新理论方法投入工业级编程使用之前,必须完成一项强制性步骤——即在给定的测试数据集上对其可靠性进行实际验证。您的任务是:将近似算法所得结果与真实数据进行对比。
您将获得 $ n $ 个值 $ a_t $、整数 $ T $ 和实数 $ c $;此外还给出 $ m $ 个时刻 $ p_j ( 1 \le j \le m $),我们关心每个时刻 $ p_j $ 对应的过去 $ T $ 秒内的请求平均值。请实现两种算法:
第一种算法按定义直接计算,即使用公式 ;
第二种算法则按上述描述计算平均值。
请输出两种算法在每个 $ p_j $ 处所得的值,并按公式 计算第二种算法的相对误差,其中 approx 是第二种(近似)算法所得值,real 是第一种(精确)算法所得值。
输入格式
The first line contains integer n (1 ≤ n ≤ 2·105), integer T (1 ≤ T ≤ n) and real number c (1 < c ≤ 100) — the time range when the resource should work, the length of the time range during which we need the mean number of requests and the coefficient c of the work of approximate algorithm. Number c is given with exactly six digits after the decimal point.
The next line contains n integers a__t (1 ≤ a__t ≤ 106) — the number of queries to the service at each moment of time.
The next line contains integer m (1 ≤ m ≤ n) — the number of moments of time when we are interested in the mean number of queries for the last T seconds.
The next line contains m integers p__j (T ≤ p__j ≤ n), representing another moment of time for which we need statistics. Moments p__j are strictly increasing.
第一行包含整数 n(1 ≤ n ≤ 2⋅105)、整数 T(1 ≤ T ≤ n)和实数 c(1 < c ≤ 100)——分别表示资源应工作的总时间范围、我们需要计算平均请求数的时间段长度,以及近似算法中使用的系数 c。数 c 以小数点后恰好六位的形式给出。
下一行包含 n 个整数 at(1 ≤ at ≤ 106)——表示每个时刻 t 向服务发出的查询次数。
再下一行包含整数 m(1 ≤ m ≤ n)——表示我们关心其过去 T 秒内平均查询次数的时刻个数。
最后一行包含 m 个整数 pj(T ≤ pj ≤ n),表示我们需要统计其过去 T 秒内平均查询次数的其他时刻。这些时刻 pj 严格递增。
输出格式
Print m lines. The j-th line must contain three numbers real, approx and error, where:
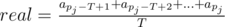 is the real mean number of queries for the last T seconds;
- approx is calculated by the given algorithm and equals mean at the moment of time t = p__j (that is, after implementing the p__j-th iteration of the cycle);
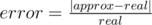 is the relative error of the approximate algorithm.
The numbers you printed will be compared to the correct numbers with the relative or absolute error 10 - 4. It is recommended to print the numbers with at least five digits after the decimal point.
输出 m 行。第 j 行必须包含三个数:real、approx 和 error,其中:
- 是最后 T 秒内查询次数的真实均值;
- approx 由给定算法计算得出,且等于时间点 t = p__j(即执行完第 p__j 次循环迭代后)时刻的 mean 值;
- 是该近似算法的相对误差。
您所输出的数值将与正确数值在相对误差或绝对误差不超过 10 ⁻⁴ 的条件下进行比对。建议输出的数字保留至少五位小数。
输入输出样例
输入#1
1 1 2.000000
1
1
1
输出#1
1.000000 0.500000 0.500000
输入#2
11 4 1.250000
9 11 7 5 15 6 6 6 6 6 6
8
4 5 6 7 8 9 10 11
输出#2
8.000000 4.449600 0.443800
9.500000 6.559680 0.309507
8.250000 6.447744 0.218455
8.000000 6.358195 0.205226
8.250000 6.286556 0.237993
6.000000 6.229245 0.038207
6.000000 6.183396 0.030566
6.000000 6.146717 0.024453
输入#3
13 4 1.250000
3 3 3 3 3 20 3 3 3 3 3 3 3
10
4 5 6 7 8 9 10 11 12 13
输出#3
3.000000 1.771200 0.409600
3.000000 2.016960 0.327680
7.250000 5.613568 0.225715
7.250000 5.090854 0.297813
7.250000 4.672684 0.355492
7.250000 4.338147 0.401635
3.000000 4.070517 0.356839
3.000000 3.856414 0.285471
3.000000 3.685131 0.228377
3.000000 3.548105 0.182702
输入解题思路,AI测评打分。不知道怎么写?