

CF202B.Brand New Easy Problem
普及+/提高
通过率:0%
时间限制:2.00s
内存限制:256MB


AC君温馨提醒
该题目为【codeforces】题库的题目,您提交的代码将被提交至codeforces进行远程评测,并由ACGO抓取测评结果后进行展示。由于远程测评的测评机由其他平台提供,我们无法保证该服务的稳定性,若提交后无反应,请等待一段时间后再进行重试。
题目描述
A widely known among some people Belarusian sport programmer Lesha decided to make some money to buy a one square meter larger flat. To do this, he wants to make and carry out a Super Rated Match (SRM) on the site Torcoder.com. But there's a problem — a severe torcoder coordinator Ivan does not accept any Lesha's problem, calling each of them an offensive word "duped" (that is, duplicated). And one day they nearely quarrelled over yet another problem Ivan wouldn't accept.
You are invited to act as a fair judge and determine whether the problem is indeed brand new, or Ivan is right and the problem bears some resemblance to those used in the previous SRMs.
You are given the descriptions of Lesha's problem and each of Torcoder.com archive problems. The description of each problem is a sequence of words. Besides, it is guaranteed that Lesha's problem has no repeated words, while the description of an archive problem may contain any number of repeated words.
The "similarity" between Lesha's problem and some archive problem can be found as follows. Among all permutations of words in Lesha's problem we choose the one that occurs in the archive problem as a subsequence. If there are multiple such permutations, we choose the one with the smallest number of inversions. Then the "similarity" of a problem can be written as 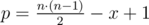 , where n is the number of words in Lesha's problem and x is the number of inversions in the chosen permutation. Note that the "similarity" p is always a positive integer.
The problem is called brand new if there is not a single problem in Ivan's archive which contains a permutation of words from Lesha's problem as a subsequence.
Help the boys and determine whether the proposed problem is new, or specify the problem from the archive which resembles Lesha's problem the most, otherwise.
一些人广为知晓的白俄罗斯竞技程序员莱沙(Lesha)决定赚些钱,以便购买一套面积大一平方米的公寓。为此,他希望在 Torcoder.com 网站上举办并执行一场“超级评级比赛”(SRM)。但这里有个问题——一位严厉的 Torcoder 协调员伊万(Ivan)拒绝接受莱沙提交的任何题目,将每一道题都斥为冒犯性的词:“duped”(即“重复的”)。某日,他们又因伊万拒绝接受的另一道题而几乎发生激烈争吵。
你被邀请担任公正的裁判,来判定该题是否确实全新,抑或伊万所言属实——即该题与以往 SRM 中已使用过的题目存在某种相似性。
你将获得莱沙所出题目的描述,以及 Torcoder.com 题库中每道存档题目的描述。每道题的描述均由若干单词构成。此外,保证莱沙的题目中不包含重复单词,而题库中某道存档题的描述则可能包含任意数量的重复单词。
莱沙的题目与某道题库题目的“相似度”定义如下:在莱沙题目所有单词的全排列中,选取一个能在该题库题目中作为子序列出现的排列;若存在多个满足条件的排列,则从中选取逆序对数最少的一个。然后,该题的“相似度”可表示为 ,其中 n 为莱沙题目中单词的个数,x 为所选排列中的逆序对数。注意,“相似度” p 恒为正整数。
若伊万的题库中没有任何一道题,其描述中包含莱沙题目单词的某个排列作为子序列,则称该题为“全新题”。
请帮助两位选手判断:所提出的题目是否为全新题;否则,请指出题库中与莱沙题目最相似(即相似度 p 最小)的那道题。
输入格式
The first line contains a single integer n (1 ≤ n ≤ 4) — the number of words in Lesha's problem. The second line contains n space-separated words — the short description of the problem.
The third line contains a single integer m (1 ≤ m ≤ 10) — the number of problems in the Torcoder.com archive. Next m lines contain the descriptions of the problems as "k _s_1 _s_2 ... s__k", where k (1 ≤ k ≤ 20) is the number of words in the problem and s__i is a word of the problem description.
All words from all problem descriptions contain no more than 10 lowercase English letters.
第一行包含一个整数 n(1≤n≤4)—— Lesha 的问题中单词的个数。
第二行包含 n 个由空格分隔的单词 —— 该问题的简短描述。
第三行包含一个整数 m(1≤m≤10)—— Torcoder.com 题库中的题目数量。接下来的 m 行每行描述一道题目,格式为“k s1 s2 … sk”,其中 k(1≤k≤20)表示该题描述中的单词个数,si 是该题描述中的一个单词。
所有题目描述中的单词均由不超过 10 个小写英文字母组成。
输出格式
If Lesha's problem is brand new, print string "Brand new problem!" (without quotes).
Otherwise, on the first line print the index of the archive problem which resembles Lesha's problem most. If there are multiple such problems, print the one with the smallest index. On the second line print a string consisting of characters [:, character | repeated p times, and characters :], where p is the "similarity" between this problem and Lesha's one. The archive problems are numbered starting from one in the order in which they are given in the input.
如果莱沙的问题是全新的,请输出字符串 “Brand new problem!”(不带引号)。
否则,在第一行输出与莱沙的问题最相似的存档问题的索引。如果有多个这样的问题,则输出索引最小的那个。在第二行输出一个字符串,该字符串由字符 [:, 后跟 p 个字符 |,再后跟字符 :] 组成,其中 p 是该问题与莱沙的问题之间的“相似度”。存档问题按输入中给出的顺序从 1 开始编号。
输入输出样例
输入#1
4
find the next palindrome
1
10 find the previous palindrome or print better luck next time
输出#1
1
[:||||||:]
输入#2
3
add two numbers
3
1 add
2 two two
3 numbers numbers numbers
输出#2
Brand new problem!
输入#3
4
these papers are formulas
3
6 what are these formulas and papers
5 papers are driving me crazy
4 crazy into the night
输出#3
1
[:||||:]
输入#4
3
add two decimals
5
4 please two decimals add
5 decimals want to be added
4 two add decimals add
4 add one two three
7 one plus two plus three equals six
输出#4
3
[:|||:]
说明/提示
Let us remind you that the number of inversions is the number of pairs of words that follow in the permutation not in their original order. Thus, for example, if the original problem is "add two numbers", then permutation "numbers add two" contains two inversions — pairs of words "numbers" and "add", "numbers" and "two".
Sequence _b_1, _b_2, ..., b__k is a subsequence of sequence _a_1, _a_2, ..., a__n if there exists such a set of indices 1 ≤ _i_1 < _i_2 < ... < i__k ≤ n that a__i__j = b__j (in other words, if sequence b can be obtained from a by deleting some of its elements).
In the first test case the first problem contains the "find the palindrome next" permutation as a subsequence, in which the number of inversions equals 1 (words "palindrome" and "next").
In the second test case there is no problem that contains a permutation of words from Lesha's problem as a subsequence.
我们提醒您,逆序对的数量是指在排列中未按原始顺序出现的单词对的数量。例如,若原始题目为“add two numbers”,则排列“numbers add two”包含两个逆序对——单词对“numbers”与“add”、“numbers”与“two”。
序列 b1,b2,…,bk 是序列 a1,a2,…,an 的一个子序列,当且仅当存在一组下标 1≤i1<i2<⋯<ik≤n,使得 aij=bj(换言之,序列 b 可通过从 a 中删除若干元素而得到)。
在第一个测试用例中,第一个题目包含子序列“find the palindrome next”,该子序列的逆序对数量为 1(单词“palindrome”与“next”)。
在第二个测试用例中,不存在任何一个题目,其文本中包含 Lesha 题目中单词的一个排列作为子序列。
输入解题思路,AI测评打分。不知道怎么写?