

CF178F3.Representative Sampling
省选/NOI-
通过率:0%
时间限制:2.00s
内存限制:256MB


AC君温馨提醒
该题目为【codeforces】题库的题目,您提交的代码将被提交至codeforces进行远程评测,并由ACGO抓取测评结果后进行展示。由于远程测评的测评机由其他平台提供,我们无法保证该服务的稳定性,若提交后无反应,请等待一段时间后再进行重试。
题目描述
The Smart Beaver from ABBYY has a long history of cooperating with the "Institute of Cytology and Genetics". Recently, the Institute staff challenged the Beaver with a new problem. The problem is as follows.
There is a collection of n proteins (not necessarily distinct). Each protein is a string consisting of lowercase Latin letters. The problem that the scientists offered to the Beaver is to select a subcollection of size k from the initial collection of proteins so that the representativity of the selected subset of proteins is maximum possible.
The Smart Beaver from ABBYY did some research and came to the conclusion that the representativity of a collection of proteins can be evaluated by a single number, which is simply calculated. Let's suppose we have a collection {_a_1, ..., a__k} consisting of k strings describing proteins. The representativity of this collection is the following value:
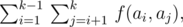
where f(x, y) is the length of the longest common prefix of strings x and y; for example, f("abc", "abd") = 2, and f("ab", "bcd") = 0.
Thus, the representativity of collection of proteins {"abc", "abd", "abe"} equals 6, and the representativity of collection {"aaa", "ba", "ba"} equals 2.
Having discovered that, the Smart Beaver from ABBYY asked the Cup contestants to write a program that selects, from the given collection of proteins, a subcollection of size k which has the largest possible value of representativity. Help him to solve this problem!
ABBYY 的智能海狸与“细胞学与遗传学研究所”有着长期的合作历史。最近,研究所的工作人员向海狸提出了一个新问题。问题如下:
给定一个包含 n 个蛋白质(彼此不一定互异)的集合。每个蛋白质是一个由小写拉丁字母组成的字符串。科学家们向海狸提出的任务是:从初始蛋白质集合中选出一个大小为 k 的子集,使得该子集中蛋白质的“代表性”尽可能大。
ABBYY 的智能海狸经过一番研究后得出结论:一个蛋白质集合的代表性可通过一个单一数值来评估,且该数值可直接计算。假设我们有一个由 k 个描述蛋白质的字符串组成的集合 {a1,…,ak},则该集合的代表性定义为如下值:
其中 f(x,y) 表示字符串 x 与 y 的最长公共前缀的长度;例如,f("abc","abd")=2,而 f("ab","bcd")=0。
因此,蛋白质集合 {"abc","abd","abe"} 的代表性为 6,而集合 {"aaa","ba","ba"} 的代表性为 2。
在得出上述结论后,ABBYY 的智能海狸请求编程杯的参赛者编写一个程序:对于给定的蛋白质集合,从中选出一个大小为 k 的子集,使其代表性达到最大可能值。请帮助他解决这一问题!
输入格式
The first input line contains two integers n and k (1 ≤ k ≤ n), separated by a single space. The following n lines contain the descriptions of proteins, one per line. Each protein is a non-empty string of no more than 500 characters consisting of only lowercase Latin letters (a...z). Some of the strings may be equal.
The input limitations for getting 20 points are:
- 1 ≤ n ≤ 20
The input limitations for getting 50 points are:
- 1 ≤ n ≤ 100
The input limitations for getting 100 points are:
- 1 ≤ n ≤ 2000
第一行输入包含两个整数 n 和 k(1 ≤ k ≤ n),以单个空格分隔。接下来的 n 行每行描述一种蛋白质,共 n 行。每种蛋白质是一个非空字符串,长度不超过 500 个字符,且仅由小写拉丁字母(a…z)组成。部分字符串可能相同。
获得 20 分的输入限制为:
- 1 ≤ n ≤ 20
获得 50 分的输入限制为:
- 1 ≤ n ≤ 100
获得 100 分的输入限制为:
- 1 ≤ n ≤ 2000
输出格式
Print a single number denoting the largest possible value of representativity that a subcollection of size k of the given collection of proteins can have.
输出一个整数,表示给定蛋白质集合中大小为 k 的子集合所能达到的最大 representativity 值。
输入输出样例
输入#1
3 2
aba
bzd
abq
输出#1
2
输入#2
4 3
eee
rrr
ttt
qqq
输出#2
0
输入#3
4 3
aaa
abba
abbc
abbd
输出#3
9
输入解题思路,AI测评打分。不知道怎么写?