

CF180A.Defragmentation
普及+/提高
通过率:0%
时间限制:1.00s
内存限制:256MB


AC君温馨提醒
该题目为【codeforces】题库的题目,您提交的代码将被提交至codeforces进行远程评测,并由ACGO抓取测评结果后进行展示。由于远程测评的测评机由其他平台提供,我们无法保证该服务的稳定性,若提交后无反应,请等待一段时间后再进行重试。
题目描述
In this problem you have to implement an algorithm to defragment your hard disk. The hard disk consists of a sequence of clusters, numbered by integers from 1 to n. The disk has m recorded files, the i-th file occupies clusters with numbers a__i, 1, a__i, 2, ..., a__i, n__i. These clusters are not necessarily located consecutively on the disk, but the order in which they are given corresponds to their sequence in the file (cluster a__i, 1 contains the first fragment of the i-th file, cluster a__i, 2 has the second fragment, etc.). Also the disc must have one or several clusters which are free from files.
You are permitted to perform operations of copying the contents of cluster number i to cluster number j (i and j must be different). Moreover, if the cluster number j used to keep some information, it is lost forever. Clusters are not cleaned, but after the defragmentation is complete, some of them are simply declared unusable (although they may possibly still contain some fragments of files).
Your task is to use a sequence of copy operations to ensure that each file occupies a contiguous area of memory. Each file should occupy a consecutive cluster section, the files must follow one after another from the beginning of the hard disk. After defragmentation all free (unused) clusters should be at the end of the hard disk. After defragmenting files can be placed in an arbitrary order. Clusters of each file should go consecutively from first to last. See explanatory examples in the notes.
Print the sequence of operations leading to the disk defragmentation. Note that you do not have to minimize the number of operations, but it should not exceed 2_n_.
本题要求你实现一个硬盘碎片整理算法。硬盘由一系列簇(cluster)组成,编号为 1 到 n 的整数。硬盘上共记录有 m 个文件,其中第 i 个文件占据的簇编号依次为 ai,1,ai,2,…,ai,ni。这些簇在硬盘上未必连续分布,但所给顺序即为该文件中数据块的逻辑顺序(即簇 ai,1 存储第 i 个文件的第一个数据块,簇 ai,2 存储第二个数据块,依此类推)。此外,硬盘上必须至少存在一个或多个未被任何文件占用的空闲簇。
你被允许执行“将编号为 i 的簇的内容复制到编号为 j 的簇”这一操作(其中 i 和 j 必须不同)。若目标簇 j 原本存有数据,则该数据将永久丢失。簇本身不会被擦除,但在碎片整理完成后,部分簇将被标记为不可用(尽管它们可能仍残留某些文件的数据块)。
你的任务是通过一系列复制操作,使得每个文件均占据一段连续的簇区域;所有文件应从硬盘起始处开始,依次紧邻存放(即第一个文件占据簇 1 到 l1,第二个文件占据簇 l1+1 到 l2,依此类推);碎片整理完成后,所有空闲(未使用)簇必须全部位于硬盘末尾。文件之间的排列顺序可以任意;但每个文件内部的簇必须按逻辑顺序连续存放(即从该文件的第一个簇开始,依次连续存放至最后一个簇)。详见题后示例说明。
请输出实现硬盘碎片整理所需的一系列操作。注意:你无需最小化操作次数,但总操作数不得超过 2n。
输入格式
The first line contains two integers n and m (1 ≤ n, m ≤ 200) — the number of clusters and the number of files, correspondingly. Next m lines contain descriptions of the files. The first number in the line is n__i (n__i ≥ 1), the number of clusters occupied by the i-th file. Then follow n__i numbers a__i, 1, a__i, 2, ..., a__i, n__i (1 ≤ a__i, j ≤ n). It is guaranteed that each cluster number occurs not more than once and  , that is, there exists at least one unused cluster. Numbers on each line are separated by spaces.
第一行包含两个整数 n 和 m(1≤n,m≤200),分别表示簇的数量和文件的数量。接下来的 m 行描述了各个文件。每行的第一个数为 ni(ni≥1),表示第 i 个文件所占用的簇的数量;随后是 ni 个数 ai,1,ai,2,…,ai,ni(1≤ai,j≤n)。保证每个簇编号至多出现一次,且满足 ,即至少存在一个未被使用的簇。每行中的数字以空格分隔。
输出格式
In the first line print a single integer k (0 ≤ k ≤ 2_n_) — the number of operations needed to defragment the disk. Next k lines should contain the operations' descriptions as "i j" (copy the contents of the cluster number i to the cluster number j).
第一行输出一个整数 k(0≤k≤2n)—— 整理磁盘所需的运算次数。接下来的 k 行每行应包含一个操作的描述,格式为“i j”(将编号为 i 的簇的内容复制到编号为 j 的簇)。
输入输出样例
输入#1
7 2
2 1 2
3 3 4 5
输出#1
0
输入#2
7 2
2 1 3
3 2 4 5
输出#2
3
2 6
3 2
6 3
说明/提示
Let's say that a disk consists of 8 clusters and contains two files. The first file occupies two clusters and the second file occupies three clusters. Let's look at examples of correct and incorrect positions of files after defragmentation.
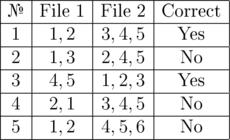
Example 2: each file must occupy a contiguous area of memory.
Example 3: the order of files to each other is not important, at first the second file can be written, and then — the first one.
Example 4: violating the order of file fragments to each other is not allowed.
Example 5: unused clusters should be located at the end, and in this example the unused clusters are 3, 7, 8.
假设一个磁盘由 8 个簇组成,并包含两个文件。第一个文件占用两个簇,第二个文件占用三个簇。我们来看一下整理碎片(defragmentation)后文件位置的正确与错误示例。
示例 2:每个文件必须占据一段连续的内存区域。
示例 3:文件之间的相对顺序并不重要,可以先写入第二个文件,再写入第一个文件。
示例 4:不允许破坏文件内部各片段之间的相对顺序。
示例 5:未使用的簇应位于磁盘末尾;在本示例中,未使用的簇为 3、7、8。
输入解题思路,AI测评打分。不知道怎么写?