

CF86C.Genetic engineering
省选/NOI-
通过率:0%
时间限制:2.00s
内存限制:256MB


AC君温馨提醒
该题目为【codeforces】题库的题目,您提交的代码将被提交至codeforces进行远程评测,并由ACGO抓取测评结果后进行展示。由于远程测评的测评机由其他平台提供,我们无法保证该服务的稳定性,若提交后无反应,请等待一段时间后再进行重试。
题目描述
"Multidimensional spaces are completely out of style these days, unlike genetics problems" — thought physicist Woll and changed his subject of study to bioinformatics. Analysing results of sequencing he faced the following problem concerning DNA sequences. We will further think of a DNA sequence as an arbitrary string of uppercase letters "A", "C", "G" and "T" (of course, this is a simplified interpretation).
Let w be a long DNA sequence and _s_1, _s_2, ..., s__m — collection of short DNA sequences. Let us say that the collection filters w iff w can be covered with the sequences from the collection. Certainly, substrings corresponding to the different positions of the string may intersect or even cover each other. More formally: denote by |w| the length of w, let symbols of w be numbered from 1 to |w|. Then for each position i in w there exist pair of indices l, r (1 ≤ l ≤ i ≤ r ≤ |w|) such that the substring w[l ... r] equals one of the elements _s_1, _s_2, ..., s__m of the collection.
Woll wants to calculate the number of DNA sequences of a given length filtered by a given collection, but he doesn't know how to deal with it. Help him! Your task is to find the number of different DNA sequences of length n filtered by the collection {s__i}.
Answer may appear very large, so output it modulo 1000000009.
“多维空间如今已完全过时,不像基因学问题那样流行”——物理学家沃尔如此想到,便将研究方向转向了生物信息学。在分析测序结果时,他遇到了一个关于DNA序列的问题。我们接下来将DNA序列视为仅由大写字母“A”、“C”、“G”和“T”组成的任意字符串(当然,这是一种简化模型)。
设 $ w $ 是一个较长的DNA序列,$ s_1,,s_2,,\dots,,s_m $ 是一组较短的DNA序列。我们称该组序列过滤(filters)$ w $,当且仅当 $ w $ 可被该组中的序列所覆盖。显然,对应于不同起始位置的子串可以相互重叠,甚至完全包含彼此。更严格地定义如下:记 $ |w| $ 为 $ w $ 的长度,并将 $ w $ 的字符编号为 $ 1 $ 至 $ |w| $。那么,对 $ w $ 中每个位置 $ i $,均存在一对下标 $ l,,r $(满足 $ 1 \le l \le i \le r \le |w| $),使得子串 $ w[l \dots r] $ 等于该组序列 $ s_1,,s_2,,\dots,,s_m $ 中的某一个元素。
沃尔希望计算出:给定长度 $ n $ 和给定序列集合,有多少个不同的DNA序列能被该集合过滤。但他不知如何着手求解。请帮助他!你的任务是求出长度为 $ n $、且能被集合 $ {s_i} $ 过滤的不同DNA序列的个数。
答案可能非常大,请对 $ 1000000009 $ 取模后输出。
输入格式
First line contains two integer numbers n and m (1 ≤ n ≤ 1000, 1 ≤ m ≤ 10) — the length of the string and the number of sequences in the collection correspondently.
Next m lines contain the collection sequences s__i, one per line. Each s__i is a nonempty string of length not greater than 10. All the strings consist of uppercase letters "A", "C", "G", "T". The collection may contain identical strings.
第一行包含两个整数 n 和 m(1 ≤ n ≤ 1000,1 ≤ m ≤ 10),分别表示字符串的长度以及集合中序列的个数。
接下来 m 行,每行包含集合中的一个序列 si。每个 si 是一个非空字符串,其长度不超过 10。所有字符串均由大写字母 "A"、"C"、"G"、"T" 组成。该集合中可能包含相同的字符串。
输出格式
Output should contain a single integer — the number of strings filtered by the collection modulo 1000000009 (109 + 9).
输出应为一个整数——被该集合过滤的字符串数量对 1000000009(109+9)取模的结果。
输入输出样例
输入#1
2 1
A
输出#1
1
输入#2
6 2
CAT
TACT
输出#2
2
说明/提示
In the first sample, a string has to be filtered by "A". Clearly, there is only one such string: "AA".
In the second sample, there exist exactly two different strings satisfying the condition (see the pictures below).
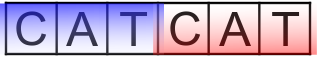
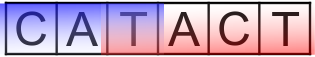
在第一个样例中,字符串需按字符 “A” 进行过滤。显然,满足条件的字符串仅有一个:“AA”。
在第二个样例中,恰好存在两个不同的字符串满足该条件(见下方图片)。
输入解题思路,AI测评打分。不知道怎么写?